The Junior's Guide to Agentic Engineering
I’ve spent the last year getting handed projects that look like a hallucination in code form. I’ve written several posts about moving from hand-coding to agentic engineering; this is the practical one. It’s for new hires and for the non-technical folks building software with AI, and it exists because reviewing that kind of work has been causing me physical pain.
By agentic engineering I mean: you tell an AI agent what you want through software specifications (spec-driven development), it writes and runs the code, and you review the result instead of typing it yourself. That’s the opposite of vibe coding, where you prompt an agent to do things with no concrete criteria for what you want done.
Horror Stories
I’ve worked on dozens of codebases in the past year that were “vibe coded”—they claimed to use agentic engineering but clearly didn’t internalize their specifications before applying them.
I get handed multi-thousand-line pull requests on a regular basis now. Reviewing one means I run an agent over the diff to surface the worst of it, then I put my own eyes on the parts that actually matter. That part works. What doesn’t work is when the shape of the project fights me before I ever get to the logic.
No Clear Project Structure
Project files are scattered everywhere, or consolidated into a few gigantic files. I’ve seen projects that are seven files, each thousands of lines long, with no utils, no helpers, and no layering of any kind. Finding the entry point becomes a scavenger hunt for you and for the agent, so every bug fix and every extension costs more than it should.
Worse, when nothing gets factored out you end up with the same function written three different ways in three different places. Duplicated logic is worse than no abstraction at all: the bug fix now has to happen three times, and one always gets missed.
Do this instead: before you write a line, have the agent map the repo and tell you where each new file belongs. If it can’t answer that, you don’t have a structure yet.
Lack of Coherent Documentation
Documentation is either nonexistent or a firehose. On one end you get no docstrings and no comments explaining the clever AI code. On the other you get manifestos and plan files that agents wrote for themselves, spread across so many markdown files that nobody can parse the project. My personal favorite is the architecture guide whose Mermaid diagram looks like Charlie Day’s conspiracy board in It’s Always Sunny in Philadelphia.
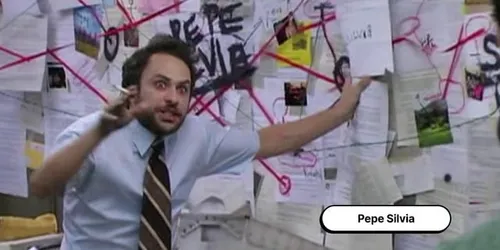
Do this instead: make docstrings part of the validation step, whether that’s OpenSpec or your own framework’s config. For architecture or UML diagrams, take the time to write them by hand, then pass them into your spec-driven workflow as context.
No Code Rules, Formatters, or Linting
The diagnostics panel lights up like a Christmas tree the moment you open the editor. But look for the rules of the codebase and you find nothing. Linters and formatters have been standard on enterprise teams for decades. Skipping them on a project other people have to read just makes everyone’s life harder.
Do this instead: spend ten minutes on day one. Initialize pre-commit, add the linters your language already agrees on, and wire it into CI. The agent will follow whatever you set; it has no opinion about your indentation.
Missing AGENTS.md, Rules, or Skills
People use AI for everything but never tell it how to work. Without clear rules of engagement the project runs on autopilot, whether you’re in the loop or not. Nail those rules down and you can churn out software fast enough to be comfortable one-shotting features and fixes you’d normally sign off on by hand.
Do this instead: open AGENTS.md today with three things in it: how to run the tests, how to run the linter, and what the agent is never allowed to touch. That’s already a useful file. Grow it every time the agent gets something wrong. Treat it like a bonsai: prune it as the project grows.
How to Level Up
You didn’t come here for pseudo-intellectual talk about what’s wrong; you came to see how to make agentic engineering a pleasure for everyone developing, reviewing, and testing the software.
Use a Spec-Driven Development Framework
I use OpenSpec because it’s lightweight and minimal, but the framework matters way less than the habit. Any tool that makes you write down what you want before code gets written will do the job. I use the explore mode to flesh out ideas and tighten gaps, which stops agents from making “shadow decisions” that create cognitive debt and let the codebase drift from what you asked for.
You should be able to explain every load-bearing decision in your codebase:
- Why you picked that language, framework, or library.
- Where each package is actually used.
- Whether you’re legally cleared to ship that dependency (read the SBOM).
If you hand me a multi-thousand-line PR and can’t walk me through the decisions in it, I’m not going to tear you apart. I’ve had reviewers do that to me as a junior and it’s the worst possible way to learn anything. Instead we get on a call, I ask you questions about the codebase, and you get a kind but honest note that I need that walkthrough before I can review your work properly. Explaining the change is part of the job now. The agents write most of the code; knowing what it does is your part.
Make Sure You Can Read the Code
Agents love to be clever. They’ll slip in long one-liners with variable names that would make Uncle Bob sad. I want code structured clearly enough that I can open any project and follow the main paths within an hour.
This gets easier with time, but you can help yourself by reading the code, especially as a new developer. If you don’t understand a line, grill the agent until it’s written in a way you do. The same thing that lets you build without a CS degree will bite you the first time something breaks and you can’t reason about why.
Keep the Agent on a Tight Leash
You need to define exactly how the agent works across requests, so the codebase stays predictable no matter which session touched it last. I encode my own habits into AGENTS.md: what has to be linted, what has to be tested, which commands the agent may never run on its own.
Here’s the shape of it. The tier rule is straight out of my homelab AGENTS.md:
## Two tiers, one rule

| Tier  | What                    | Needs                              |
|-------|-------------------------|------------------------------------|
| read  | observes, never changes | nothing                            |
| apply | changes hosts           | vault access + explicit APPLY=1    |

The rule: `--check --diff` first, read the plan, then re-run with `APPLY=1`.
A PreToolUse hook denies any apply-tier command that lacks the prefix.

## Code Formatting
`pre-commit run --all-files` must pass before anything gets pushed. The
PostToolUse hook runs the same checks on every file an agent edits, so an
agent never leaves behind something the hook would reject anyway.
That’s the whole idea. The agent states its intent in the same command that acts, and the tooling refuses to play when it doesn’t. Write your version for your stack.
My Personal SDLC Workflow
Four phases, and I only need to touch the keyboard in two of them.
1. The Spec Phase
Explore the idea and flesh it out. The point here is to kill agent-made decisions before they become code. It’s the cheapest place to be critical: no lines written yet, and the whole conversation is still inside the context window.
Do it right and you can feed that same conversation straight into the propose step. You can also shape how the specs get written through the config file. I lean on this hard, matching my specs to a subset of AGENTS.md so the exit criteria are baked in: all tests passing, linter clean, security checks green.
2. The Implementation Phase
The human is out of the loop here unless the agent hits a snag. To stay context-efficient I start a brand new session instead of reusing the one that wrote the proposal. Run apply and let it work the task list. I step in only when the agent gets stuck, tries to run a command that isn’t allowlisted, or hits a gap in the spec.
3. The Verification Phase
How hard you look here depends on what the change can break. For small, low-risk work I run a manual pass and confirm it captured my intent. For anything touching privacy, security, or money, I want an agent review and a human review.
The reviewer I use day to day is ponytail. It’s a skill that reviews code for exactly one thing: over-engineering. /ponytail-review walks the diff and hunts what can be deleted, the reinvented standard library, the dependency that buys nothing, the abstraction with one implementation. /ponytail-audit runs the same sweep across a whole repo. It reports and changes nothing, which is exactly what I want from a reviewer that isn’t me.
One caveat on agent-reviewing-agent code: they share blind spots. The reviewer read the same spec and the same model of the world as the writer, so it will happily bless a change that was wrong from the start. Use it to catch missing tests, style drift, and unhandled edge cases. Use a human for judgment.
4. Close Out
Sync and archive the specs. People argue about whether specs belong in the repo. I’ve changed my mind on this one. Code shows how a thing works, through comments, docstrings, and the logic itself, but it doesn’t preserve why. Six months later someone can change the meaning of a function without ever knowing what it was meant to do. The archived spec is the only record of the original intent.
Scale the Ceremony to the Blast Radius
A throwaway script or a weekend project does not need a proposal, a spec, and an archive. That’s how you end up hating this process. Run the full loop on anything other people maintain or that touches data, money, or auth. For the rest, a good conversation and a manual test is fine.
Conclusion
I didn’t adopt this workflow to be extra or to add steps to my day. I adopted it because the alternative is a codebase that nobody, agent or human, can explain.
We’re moving from writing syntax to managing intent. The bottleneck in software development isn’t typing anymore, it’s saying clearly what the code should do. So stop prompting and start engineering the intent.